Proximal
Correct the student's own response while preserving its structure and style.
LANGUAGE MODEL POST-TRAINING
Minimal corrections to student reasoning.
Binary supervision that learns from both sides.
The University of Hong Kong
Overview
The student's own mistakes are a starting point for targeted knowledge injection.
Injecting new reasoning knowledge into Large Language Models (LLMs) via post-training often induces catastrophic forgetting. Recent studies emphasize the importance of on-policy data in mitigating forgetting, but suggest that explicit KL regularization does not explain the observed retention benefits. We study the implicit regularization induced by reference-relative reward objectives: gradient analysis reveals adaptive attenuation of updates, while controlled comparisons on the same rectified data demonstrate improved capability retention. This motivates our Surgical Post-Training (SPoT), a post-training framework designed to optimize reasoning efficiently while preserving prior knowledge.
SPoT consists of (1) a data rectification pipeline employing an Oracle to surgically correct erroneous steps via minimal edits, generating proximal on-policy data; and (2) a reward-based binary cross-entropy objective that learns from both corrected and erroneous responses.
Empirically, with only 4k rectified math pairs, SPoT improves Qwen3-8B's accuracy by 6.3 percentage points on average across 9 in-domain and out-of-domain tasks, requiring merely 16 minutes of model training on 8 × H800 GPUs. We further validate SPoT through Connect4 post-training, where it improves both game and mathematical reasoning while retaining instruction-following capabilities. Moreover, SPoT provides a superior initialization for subsequent reinforcement learning, enabling further gains in reasoning performance.
Read the full manuscript →Correct the student's own response while preserving its structure and style.
Learn from corrected and erroneous reasoning through separate positive and negative terms.
Adapt sample-wise updates using rewards measured against the initial model.
Method
Offline Oracle corrections yield proximal response pairs. Binary optimization then learns from both the correction and the mistake.
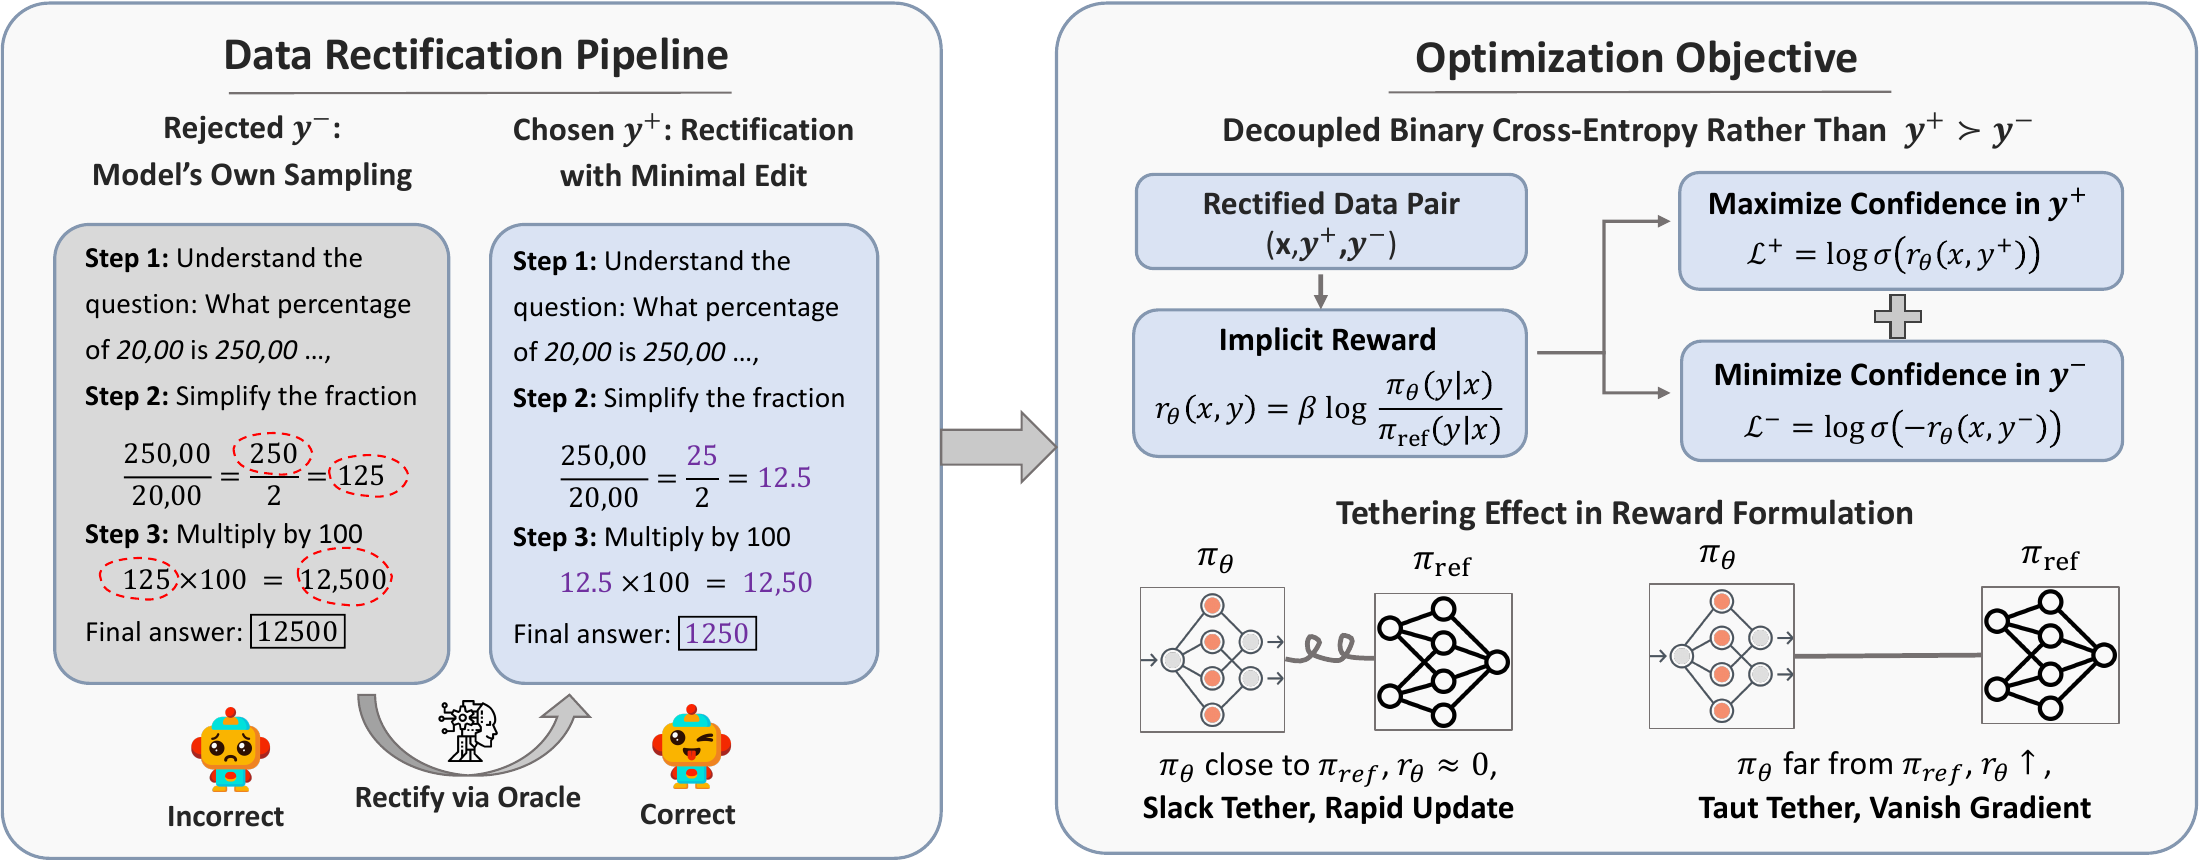
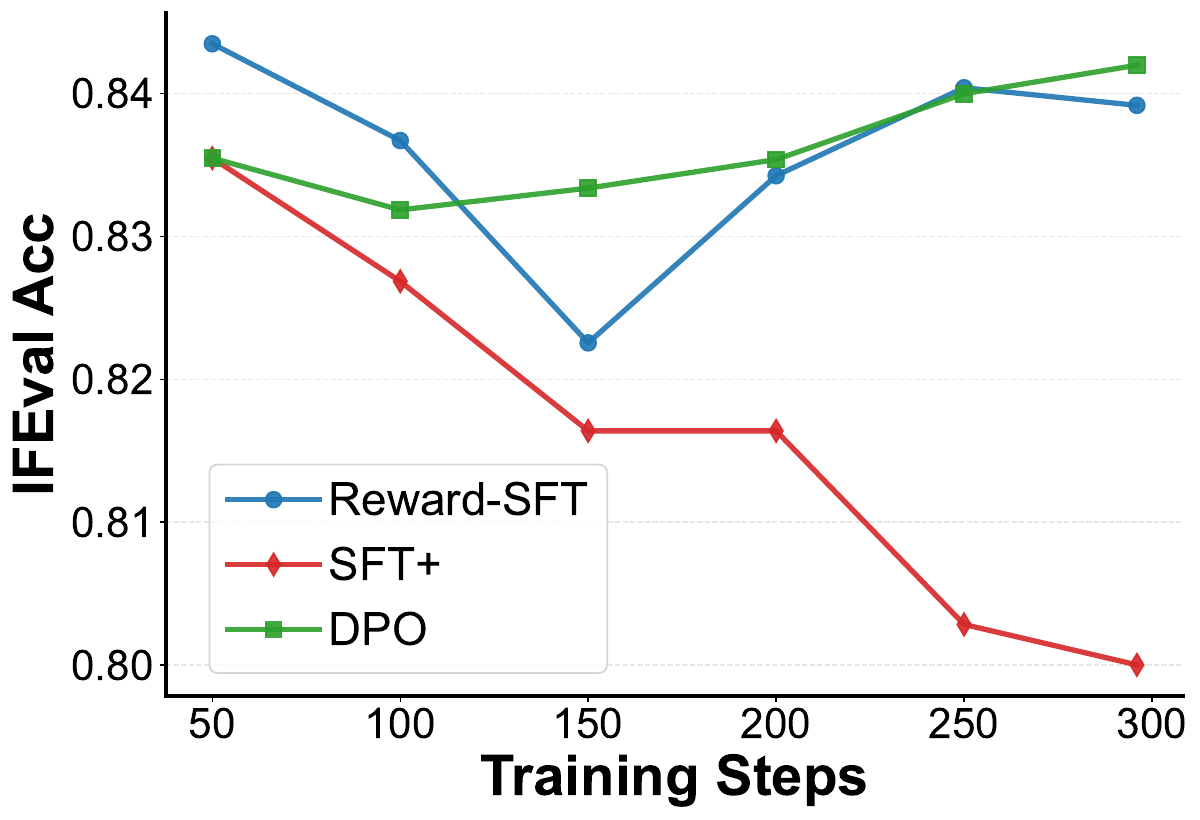
SPoT-BCE uses a fixed decision threshold. SPoT-BCO adapts it using a running reward mean, which can sustain positive-sample updates. In our Qwen3-8B experiments, BCE achieves higher IFEval accuracy, while BCO achieves higher average math accuracy.
Reference-relative rewards provide sample-wise adaptive attenuation; the experiments demonstrate improved retention in the evaluated settings. BCE and BCO are existing loss forms, combined here with proximal reasoning rectification.
Results
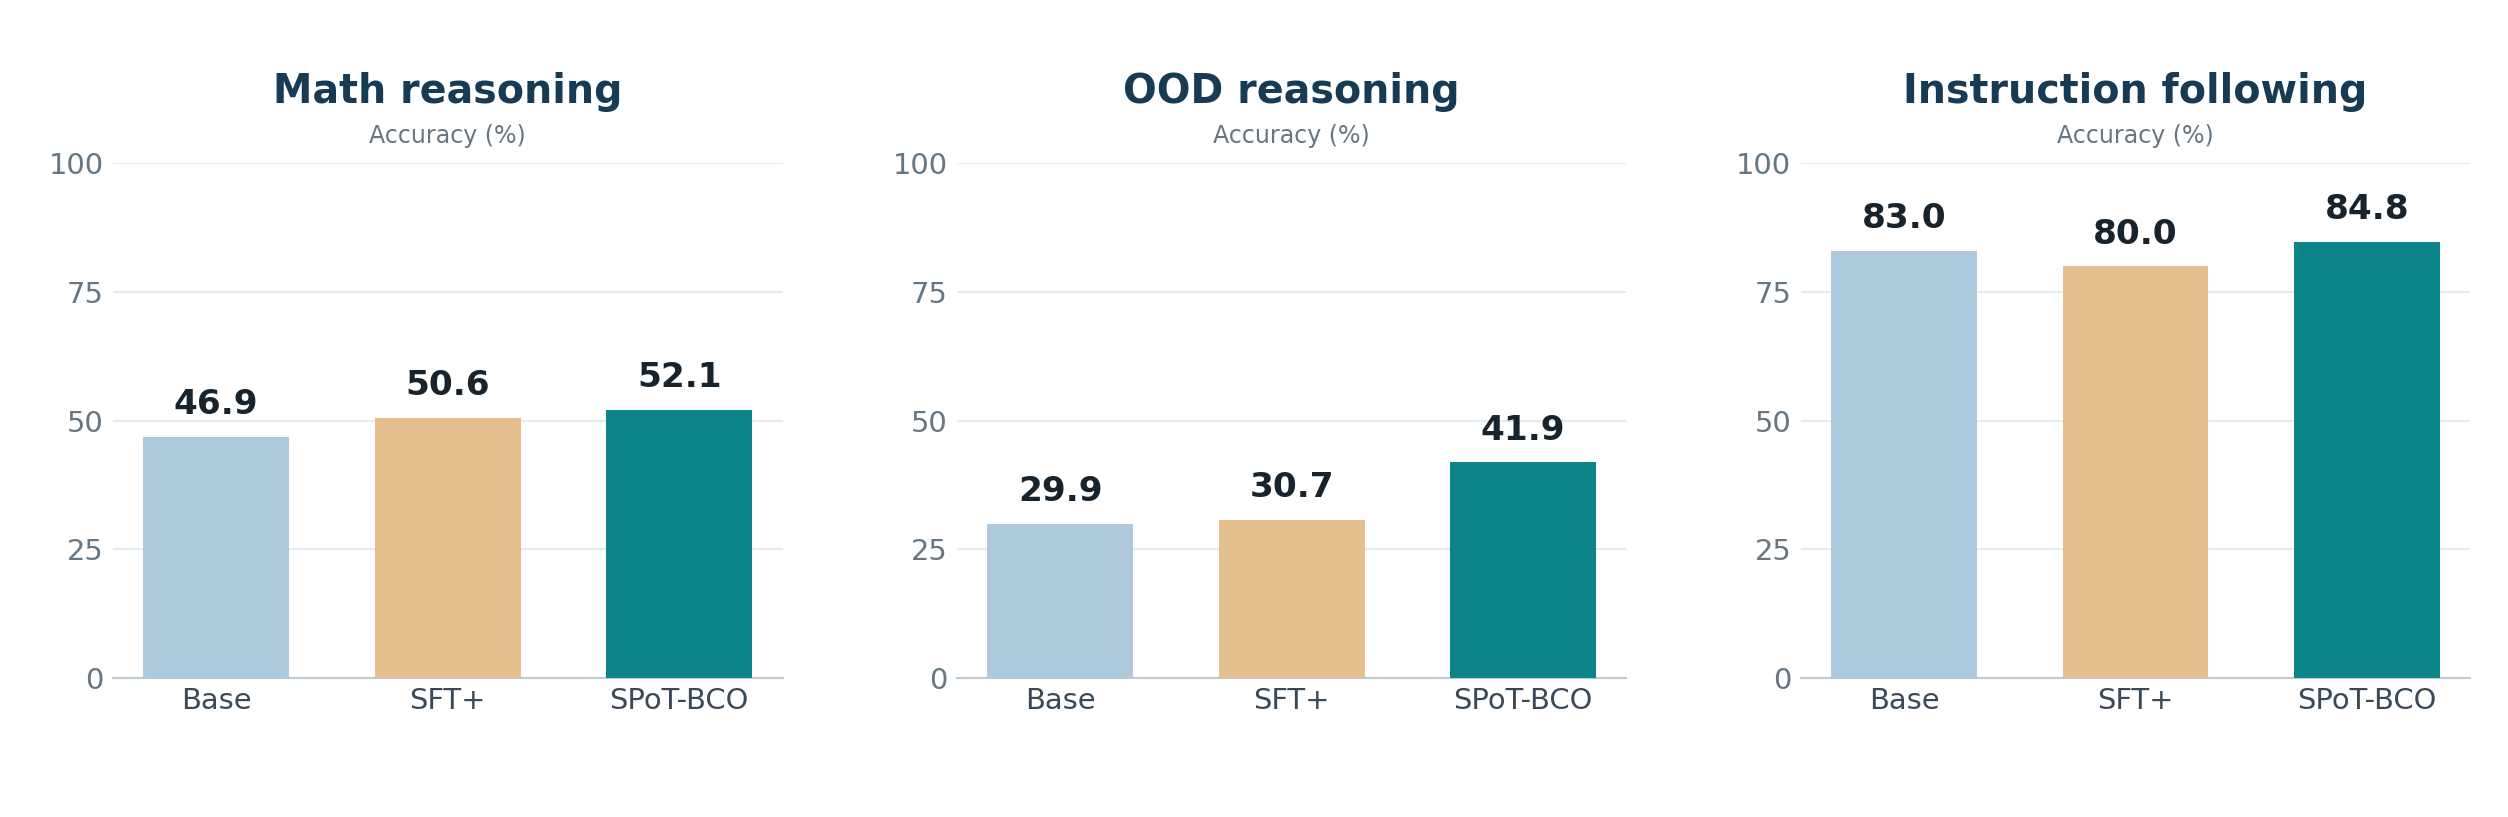
Main comparisons on two instruction-tuned backbones, spanning mathematical reasoning, OOD reasoning and instruction following.
4k math pairs · non-thinking mode · Tables 1–2
Three methods shown for a direct comparison. Every evaluated method is included below. Bar lengths share a 0–100 scale.
Swipe the table to see all columns →
| Method | Math avg. | OOD avg. | IFEval | Overall avg. |
|---|
Overall average: unweighted mean across 9 benchmarks (6 math, 2 OOD, 1 instruction-following). Bold indicates the highest value in a column. Figures use the September 2026 manuscript.
| Method | AIME24 | AIME25 | AMC23 | Math500 | Minerva | Olympia | GPQA-D | Connect4 | IFEval |
|---|
Baseline definitions. SFT learns from direct Oracle responses; RFT learns from correct student-generated responses; SFT+ learns from the rectified positive responses. DFT, DPO, Smaug, KTO, Reward-SFT, and SPoT use the rectified data in the Qwen3-8B objective comparison. SPoT-BCE achieves the highest IFEval score there; SPoT-BCO achieves the highest overall and math averages.
Training setup. English subset of DAPO-Math-17k; Gemini 2.5 Pro as the rectification Oracle. Main comparisons use 2 epochs, a context length of 8,192, and β = 0.1. Qwen3-8B uses 4k pairs; Llama-3.1-8B-Instruct uses 1.5k pairs.
Math: AIME24/25, AMC23, Math500, Minerva, and Olympia (OlympiadBench). OOD: GPQA-Diamond and Connect4. General: IFEval. Evaluation settings are shared across methods for each backbone. Qwen3-8B uses non-thinking mode. See the manuscript for sampling, variability, and hyperparameter-search details.
Analysis
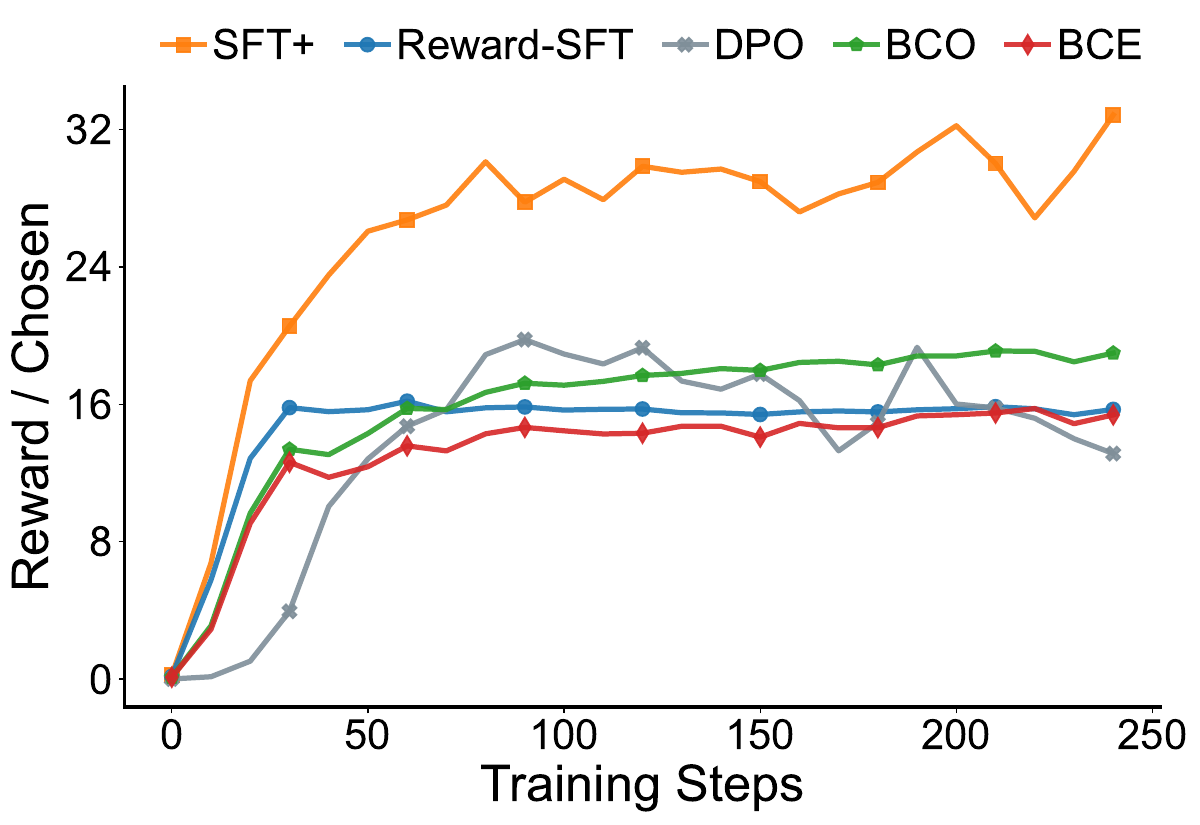
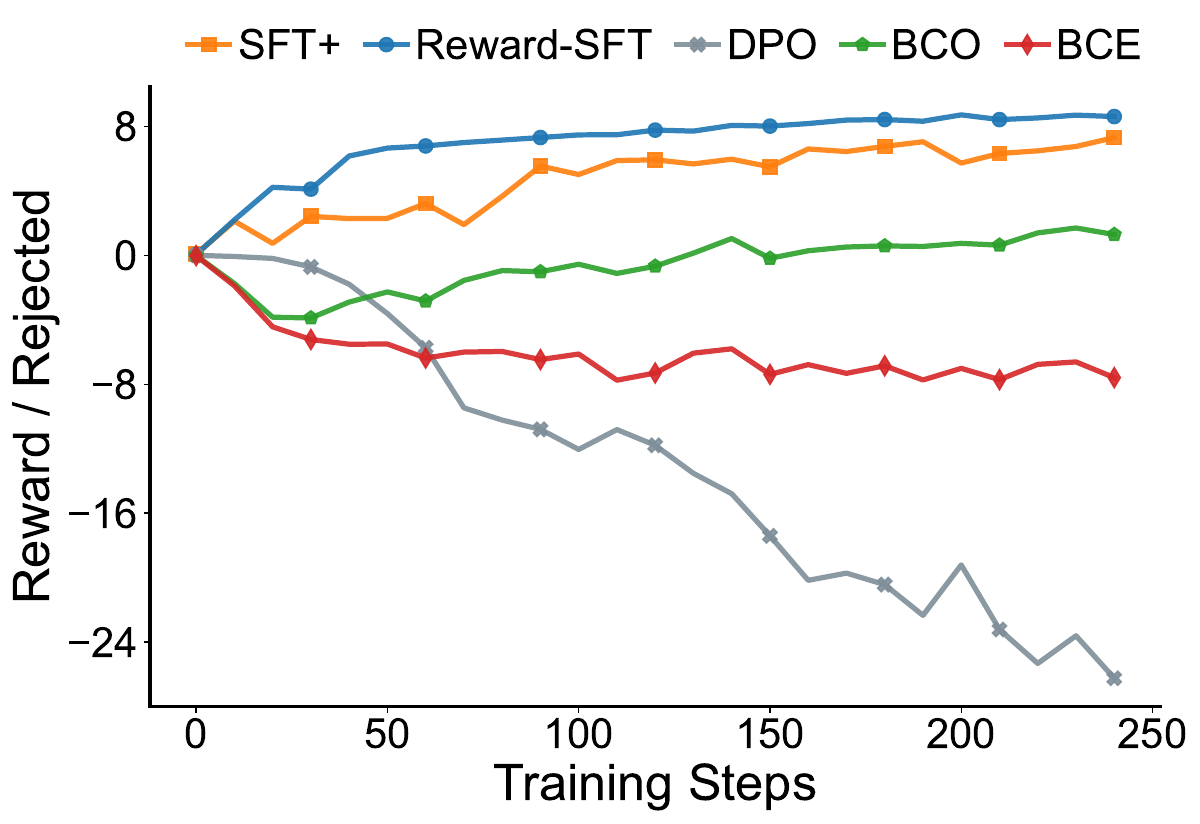
Positive-only training can also reinforce similar errors. The reference-relative formulation and negative supervision play complementary roles.
Extensions
Separate experiments test downstream reinforcement learning and post-training on game reasoning.
Initializing GRPO with SPoT improves all five reported benchmarks over GRPO alone.
| Accuracy (%) | GRPO | SPoT + GRPO |
|---|---|---|
| AIME24 | 36.3 | 41.3 |
| AIME25 | 28.8 | 36.7 |
| AMC23 | 77.5 | 85.9 |
| Connect4 | 7.7 | 29.4 |
| IFEval | 81.2 | 82.1 |
IFEval remains below the original Base (83.0). The benefit here is relative to GRPO alone.
With 1,000 Oracle-rectified game examples, SPoT improves Connect4 reasoning and retains instruction following.
| Accuracy (%) | Base | SFT | SPoT |
|---|---|---|---|
| Connect4 | 10.9 | 43.9 | 46.7 |
| AIME24 | 22.1 | 24.0 | 25.4 |
| AIME25 | 19.4 | 20.6 | 21.3 |
| Math500 | 82.8 | 84.8 | 84.4 |
| IFEval | 83.0 | 80.4 | 83.3 |
Separate training setting. GPT-5.5 is the Oracle; final-answer filtering is omitted to test tolerance to Oracle errors.
Experiments focus on models up to 8B and text-based mathematical and game reasoning. Results depend on Oracle quality. Larger models, multimodal reasoning, code generation, and agentic tasks remain future work.
Resources
The manuscript contains the results shown here. The public preprint and released artifacts reflect the earlier release.
Citation
BibTeX for the public arXiv preprint. Its title differs from the current research manuscript.
@article{lin2026surgical,
  title   = {Surgical Post-Training: Proximal On-Policy Distillation
             for Reasoning with Knowledge Retention},
  author  = {Wenye Lin and Kai Han},
  journal = {arXiv preprint arXiv:2603.01683},
  year    = {2026},
  url     = {https://arxiv.org/abs/2603.01683}
}